

To debug missing pages in a crawl, do not assume the symptom is an indexing problem. The first question is narrower: why did this crawler, with this scope and configuration, fail to discover or accept an expected URL? That distinction keeps a team from changing robots rules, canonicals, or content before it has isolated the real break in the crawl path.
The Screaming Frog tutorial that surfaced this opportunity focuses on debugging a crawler that does not find an expected URL. This guide adds a crawler-agnostic operating workflow: separate scope from discovery, access from indexing, rendering from response failures, and a proposed fix from a proven recrawl result.
Start With the Right Missing-Page Symptom
Write down the URL that is absent, the crawl run where it should have appeared, and the evidence that says it belongs in scope. A URL can be missing for several different reasons, and each needs a different first check.
| What you see | What it usually means | Start here |
|---|---|---|
| The URL is absent from a site-audit crawl | The crawler did not discover it, was not allowed to request it, or filtered it out | Scope, seed URLs, internal links, sitemap, and crawl rules |
| The URL is in the crawl but marked non-indexable | The crawler found it, but a technical signal changes whether it should represent a page in search | Robots, noindex, canonical, response, and sitemap alignment |
| The URL is absent from Google | Search discovery and processing may be the issue, but a site crawl alone cannot prove it | Crawlability, canonicalization, URL inspection, and search-facing evidence |
| A whole directory is missing | The problem is likely configuration, access, routing, or a shared template behavior | Start URLs, include and exclude patterns, authentication, redirects, and rendering |
Check Crawl Scope Before You Blame the Page
The fastest false positive is a URL that was never eligible for the crawl. Confirm the run's start URLs, allowed hostnames, include and exclude patterns, crawl depth, URL parameters, authentication state, and JavaScript-rendering setting before investigating the target page itself.
For each missing URL, build a small evidence card:
| Evidence to capture | Why it matters | Useful next action |
|---|---|---|
| Exact target URL and expected page type | Prevents a category URL, pagination variant, or redirected legacy URL from being treated as the wrong page | Compare it with the canonical page and intended inventory |
| Crawl start point and allowed paths | Reveals a URL that sits outside the initial site graph or a restricted directory | Add a bounded seed URL or correct the crawl boundary |
| Include, exclude, and parameter rules | Explains deliberate filters and accidental pattern matches | Test the URL against the configuration before changing the site |
| Authentication and cookie requirements | Shows whether the page is invisible to an unauthenticated crawler | Use a safe, authorized crawl scope or validate the public response separately |
| Rendering mode and crawl depth | Finds pages whose links appear only after rendering or beyond the configured path | Test a small representative URL set with the needed setting |
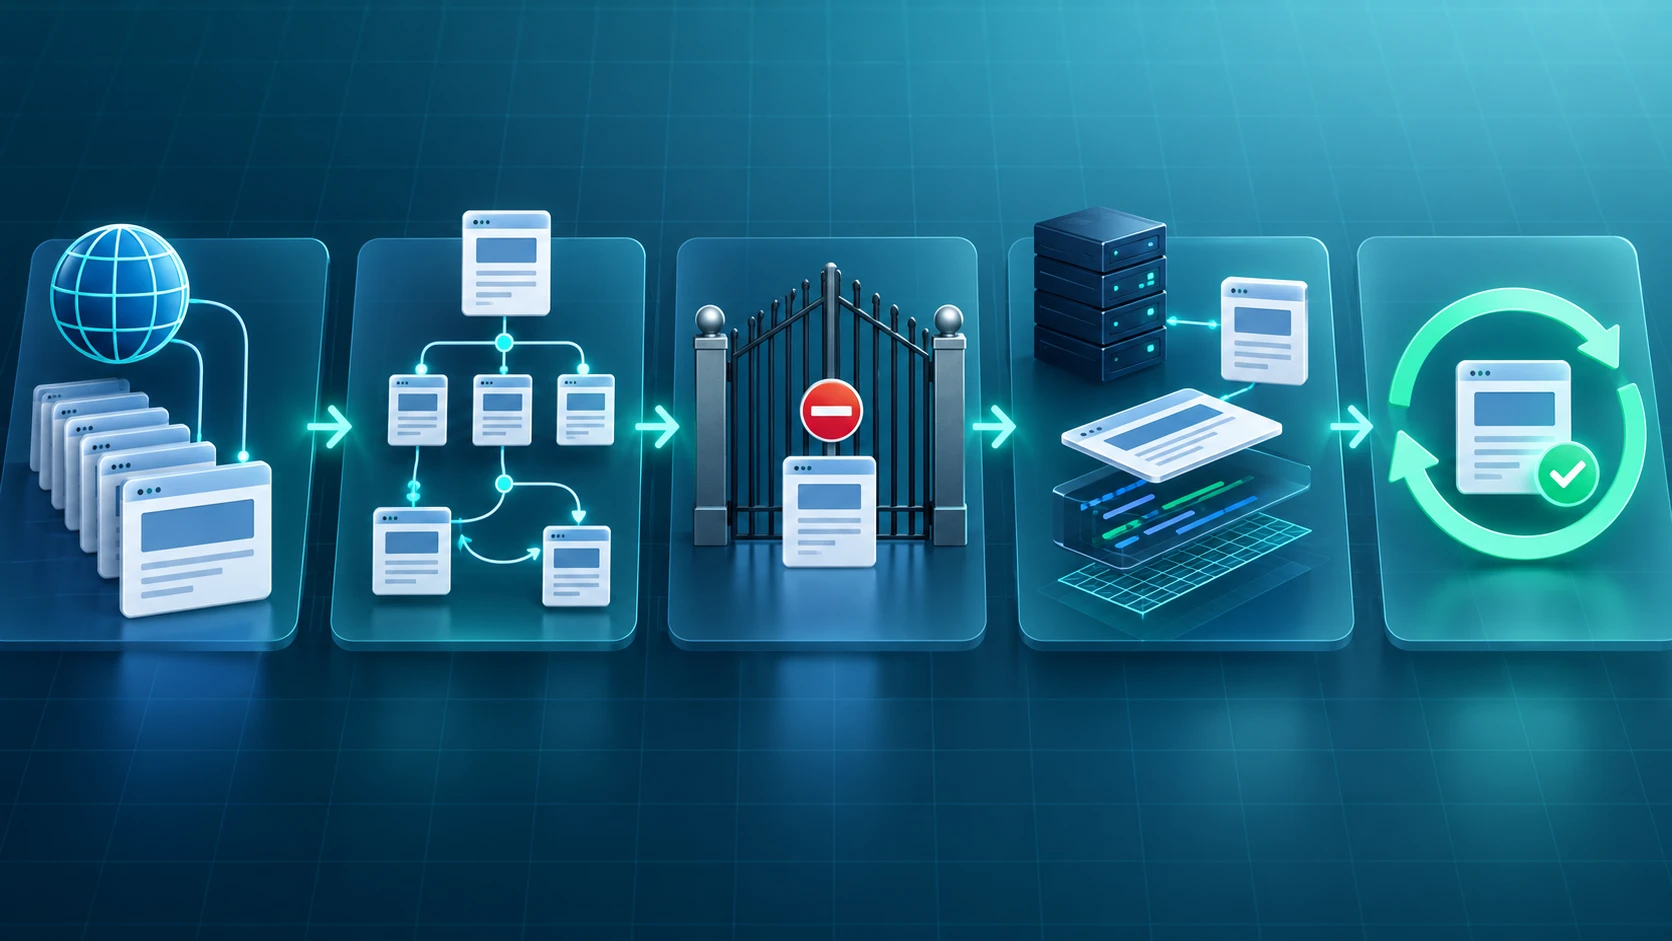
This article is intentionally different from how to crawl large websites. Large-site planning decides what a crawl should include at scale. Missing-page debugging starts after a specific URL or section should have been visible but was not.
Prove How the URL Should Be Discovered
Once the scope is correct, trace the URL's discovery path. Start with the internal page that should link to it, then compare the page's source and rendered output when JavaScript may change navigation. Check whether the URL is present in the sitemap that represents the site's preferred inventory.
Google's sitemap guidance recommends listing the canonical URLs a site wants search engines to consider. That makes a sitemap useful diagnostic evidence, but not a substitute for a crawlable internal path.
Work through these questions in order:
- Is there an intended internal link from an in-scope, reachable page to the target?
- Does that link appear in the HTML the crawler is using, or only after client-side rendering?
- Does the link resolve to the expected URL, a redirect, or a different canonical target?
- Is the target in the appropriate XML sitemap as an absolute canonical URL?
- Is the URL excluded by a parameter, a directory rule, a depth limit, or a crawler setting?
If a URL has no reasonable discovery route, the fix may be an internal-link or sitemap change. If it has a route but still disappears, the next question is whether the crawler can request and process it.
Separate Crawl Access From Indexability
Access controls answer whether a crawler can reach a URL. Indexability signals answer whether a reached URL should be considered for search. Treat them as separate columns in the diagnostic record.
Google's robots.txt documentation explains that robots rules manage crawler access; they are not a reliable way to remove a web page from search results. A page can therefore be intentionally excluded from an audit crawl, crawlable but marked noindex, or discoverable to a crawler while still being the wrong canonical representative.
| Signal | What to check | What not to conclude too quickly |
|---|---|---|
| robots.txt or crawler directives | Does a rule apply to this exact path and user agent? | A block does not prove the URL should disappear from search |
| HTTP authentication or a session gate | Does the page need authorized access or a stable cookie state? | A successful browser session does not prove an unauthenticated crawler can reach it |
| Meta robots or X-Robots-Tag | Is noindex intentional for this page type? | Noindex does not explain why the URL never appeared in a crawl |
| Canonical target | Does the page point to the preferred equivalent URL? | A canonical does not prevent a crawler from seeing the source URL |
| Sitemap state | Is the intended canonical URL listed where expected? | Sitemap presence alone does not repair broken internal discovery |
For focused technical guidance on accidental crawl blocks, see the robots.txt workflow. Use it when the actual problem is rule behavior; use this diagnostic sequence when the team still does not know which layer removed the page from the crawl.
Inspect Rendering and Server Responses
If scope, discovery, and access look correct, reproduce the request path. Compare the raw response with the rendered page for the target and the pages that should link to it. A client-side route can appear in a browser while an audit crawler sees an empty shell, a redirect, a blocked resource, or no usable internal link.
Check the response pattern across a small sample instead of one URL in isolation:
| Pattern | Likely owner | First validation |
|---|---|---|
| A template returns 4xx or 5xx responses | Engineering or platform | Request the URL, review the affected template family, and recrawl after the repair |
| The browser sees a link but the source HTML does not | Frontend or platform | Compare raw and rendered HTML for navigation, canonicals, metadata, and links |
| A redirect changes the expected destination | SEO and engineering | Confirm the redirect intent, final status, canonical, and internal-link target |
| A crawler rule filters a valid directory | SEO or technical owner | Test the exact rule against the smallest reproducible URL set |
| A login or consent flow hides the page | Product or platform | Define a safe audit boundary and verify the intended public behavior |
Google's HTTP status-code reference is useful when response patterns are involved: response outcomes change what a crawler can process, and a successful response alone does not guarantee that a page will be indexed. For rendering-specific symptoms, the JavaScript SEO workflow helps a team compare source HTML with the output users and crawlers can actually receive.
Turn the Diagnosis Into a Recrawl Test
A fix is not complete because a setting changed or a deploy passed. Before work ships, record the exact observable result that should make the URL appear in the next crawl. That makes the final recrawl a proof step instead of a hopeful re-run.
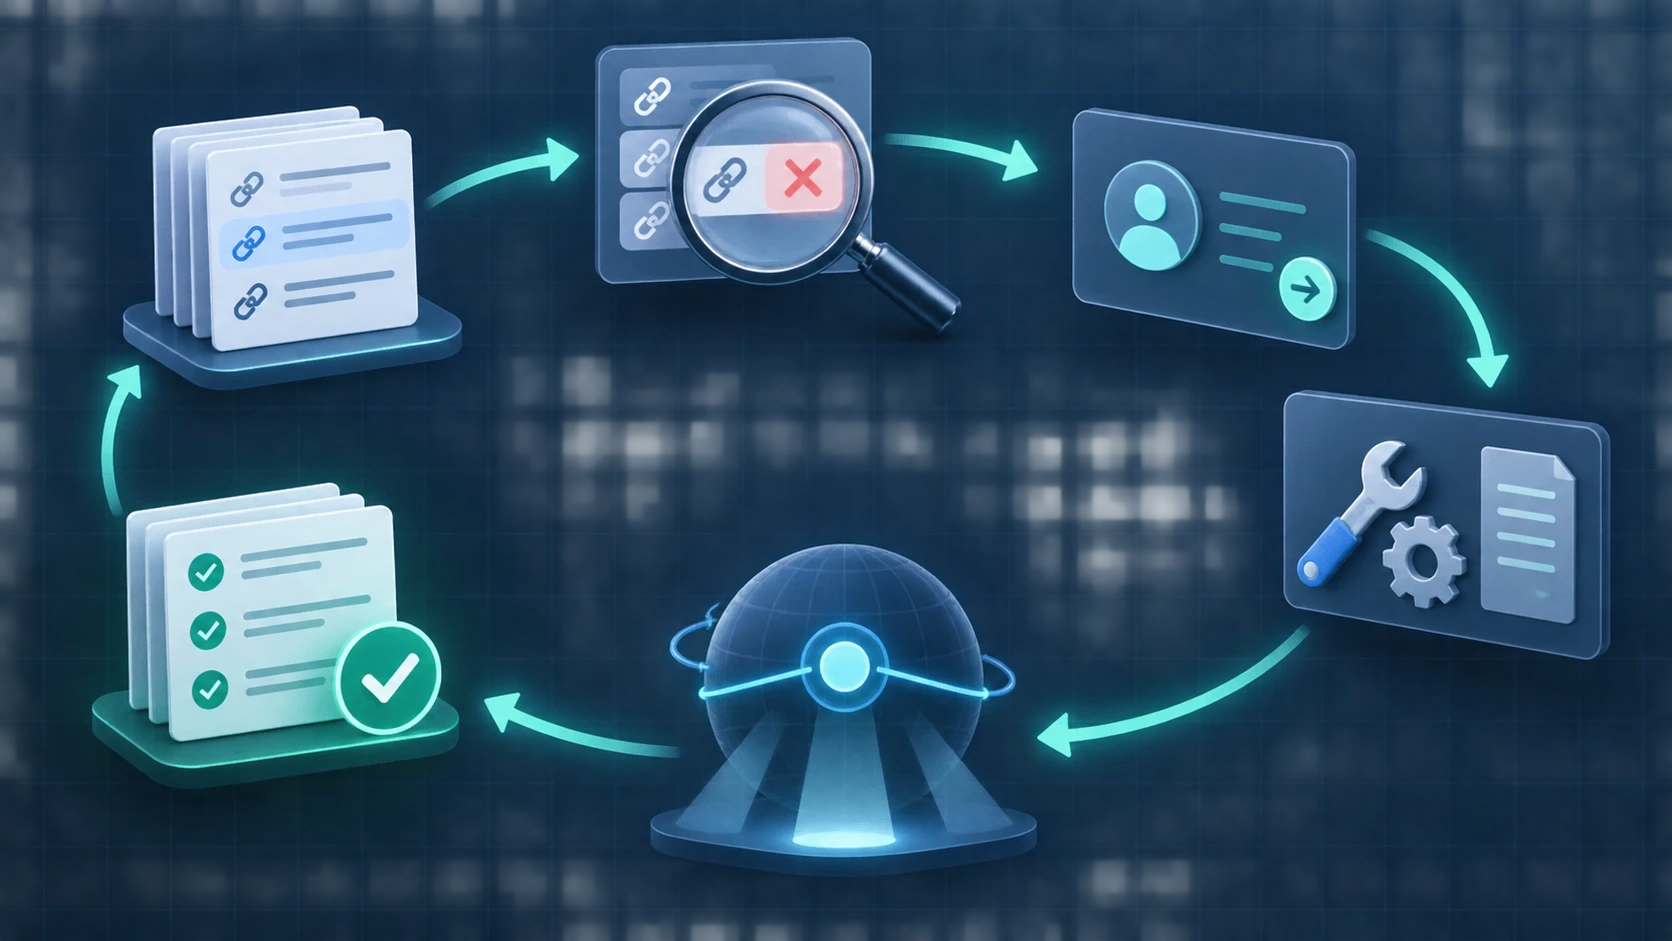
Use an owner-ready handoff like this:
| Handoff field | Example for a missing crawl URL |
|---|---|
| Affected pattern | Product pages under one locale are absent from the crawler |
| Evidence | Start URL, expected internal link, sitemap entry, raw response, rendered result, and current crawl configuration |
| Decision | Add or correct the discovery path, adjust the bounded crawl configuration, or repair the page response |
| Owner | SEO, frontend, platform, content, or localization owner |
| Acceptance criteria | The target URL is reachable through the expected path and appears with the intended status, canonical, metadata, and indexability state |
| Recrawl proof | Re-run the same scoped crawl plus a small set of template peers and compare the result with the baseline |
Searvora's SEO Spider Crawler fits at the evidence-to-action stage: organize target URL samples around responses, redirects, canonicals, metadata, internal links, sitemaps, and indexability, then give each fix an owner and a recrawl test. The goal is not a longer issue export. It is a reliable answer to why the URL was absent and proof that the correction changed the crawl.
Missing Pages in a Crawl Checklist
Use this checklist before escalating an absent URL as a technical SEO defect:
- Confirm the exact target URL and intended page type.
- Record whether the symptom is missing from the crawl, the indexable inventory, or search results.
- Check crawl scope, seeds, host rules, include and exclude patterns, parameters, depth, and authentication.
- Trace the expected internal-link path and sitemap entry.
- Separate robots and access rules from noindex and canonical signals.
- Compare raw and rendered HTML when JavaScript can alter links or page signals.
- Sample nearby URLs to decide whether the issue is isolated or template-wide.
- Assign one owner, one expected live result, and one recrawl test.
- Re-run the same bounded crawl after the change and save the before-and-after evidence.
The useful outcome is not simply that the crawler finally sees a URL. It is a repeatable explanation of why the URL was missing, which layer required a change, and how the team verified the next crawl now reflects the intended site.