
SEO for PDFs is not a reason to turn every document into a web page. Google lists PDF among the encoded file types it can index, so a useful, text-based document can be a legitimate search result. The harder job is deciding which URL should own the reader's task before two versions of the same material compete with each other.
Start with the document's job. If a reader needs to scan, compare, navigate, update, or act on the content, an HTML page is usually the stronger primary asset. If the value is a fixed-layout report, signed form, official record, or printable resource, a PDF can remain the right destination. The SEO work is then to make that decision unambiguous in headers, links, sitemaps, and follow-up checks.
Choose HTML or PDF Before You Optimize Either One
The useful question is not which format sounds more "SEO-friendly." It is whether the format serves the job the searcher actually has. Use the document itself as evidence, then choose one preferred destination for the substantive content.
| Reader or business need | Start with HTML when | Keep a PDF when | Preferred search-asset decision |
|---|---|---|---|
| A how-to, comparison, or troubleshooting task | The reader needs headings, navigation, related links, and a next action | The PDF is only a supporting download | Make the HTML page the primary source and link to the PDF as an optional resource |
| A research report or white paper | You need a summary, methodology context, updates, or several conversion paths | The fixed document is the authoritative deliverable | Publish an HTML landing page that explains the report, then decide whether the PDF or page owns the full text |
| A regulated, signed, or print-ready document | A plain-language explanation helps people find and understand it | Exact layout, pagination, or a controlled copy is the point | Keep the PDF, but give it a clear owner page and contextual internal links |
| Reused content in two formats | The same core answer would otherwise appear twice | A download is still required for offline use | Choose one canonical representative instead of leaving both URLs to compete |
| A short one-off handout | The content is likely to be expanded or refreshed | The file is stable and genuinely useful on its own | Do not build a thin HTML twin just to create another URL |
This prevents a common content-operations mistake: publishing a polished article and an almost identical downloadable document, then treating a weak canonical signal as a substitute for a page-purpose decision. First decide what should rank. Then make the rest of the site reinforce that choice.
Make the PDFs You Keep Technically Legible
Google determines file type primarily from the response Content-Type header and supports PDF as an indexable encoded file type. That does not make every PDF a useful result by default. The document still needs a clear topic, readable text, an intentional URL, and a site context that helps crawlers and people understand why it exists.
Work through these checks for a PDF that should remain discoverable:
- Confirm the document can carry the answer. Select text in the file, check reading order, and make sure the important explanation is not only an image or a scan. A reader should be able to find the main claim without needing a separate hidden transcript.
- Check the live response, not only the CMS file picker. Record the final URL, status code,
Content-Type, redirect behavior, and any response directives. A file that has moved, redirects through several hops, or is served unexpectedly needs a deployment fix before it becomes a search target. - Give the file context with normal HTML links. Link to it from an owner page with an anchor that describes the resource. The owner page can explain audience, scope, update date, and what a reader should do next.
- Put only intentional indexable URLs in the sitemap. Include a PDF only when it is a preferred, useful resource. Do not use sitemap inclusion to compensate for a document that lacks a clear job or internal discovery path.
- Treat accessibility as content quality. Check a meaningful title, selectable text, logical structure, descriptive links, and a useful alternative or summary page when the document is hard to navigate.
If the PDF is a duplicate or a download that should not appear in search, control the file at the HTTP layer. Google's robots documentation explains that non-HTML resources use an X-Robots-Tag response header rather than an HTML meta robots tag. For example:
X-Robots-Tag: noindex
If the same content exists in HTML and PDF and the HTML page should be preferred, Google's canonical documentation allows a non-HTML resource to return a canonical link in its HTTP response. That can support a deliberately chosen representative, but it does not fix two pages that serve different user jobs.
Link: <https://example.com/research/report>; rel="canonical"
Use one policy intentionally. Do not layer a redirect, noindex, canonical header, sitemap entry, and internal links without agreeing on which URL users and search systems are supposed to find.
Run a PDF SEO Deployment Check
Most PDF SEO failures are deployment or ownership problems, not writing problems. Check the file and its owner page together before calling the work finished.
| Check | What to inspect | Healthy outcome |
|---|---|---|
| Response | Final status, redirect chain, Content-Type, and response headers | The intended file URL resolves cleanly and returns the policy you planned |
| Preferred URL | HTML and PDF relationship, canonical header where used, and duplicate scope | One URL clearly owns the substantive answer |
| Indexing directive | X-Robots-Tag for non-indexable files and whether crawlers can see the directive | A deliberate keep-in-search or keep-out-of-search policy, not an accidental conflict |
| Discovery | Contextual inlinks, owner page, and sitemap entry | Readers and crawlers can reach the preferred resource through relevant pages |
| Document quality | Selectable text, title metadata, reading order, links, and an accessible explanation | The file is understandable without relying on a visual scan alone |
| Measurement | URL-level baseline, release date, and a date for rechecking | The team can tell whether the preferred asset was actually selected and used |
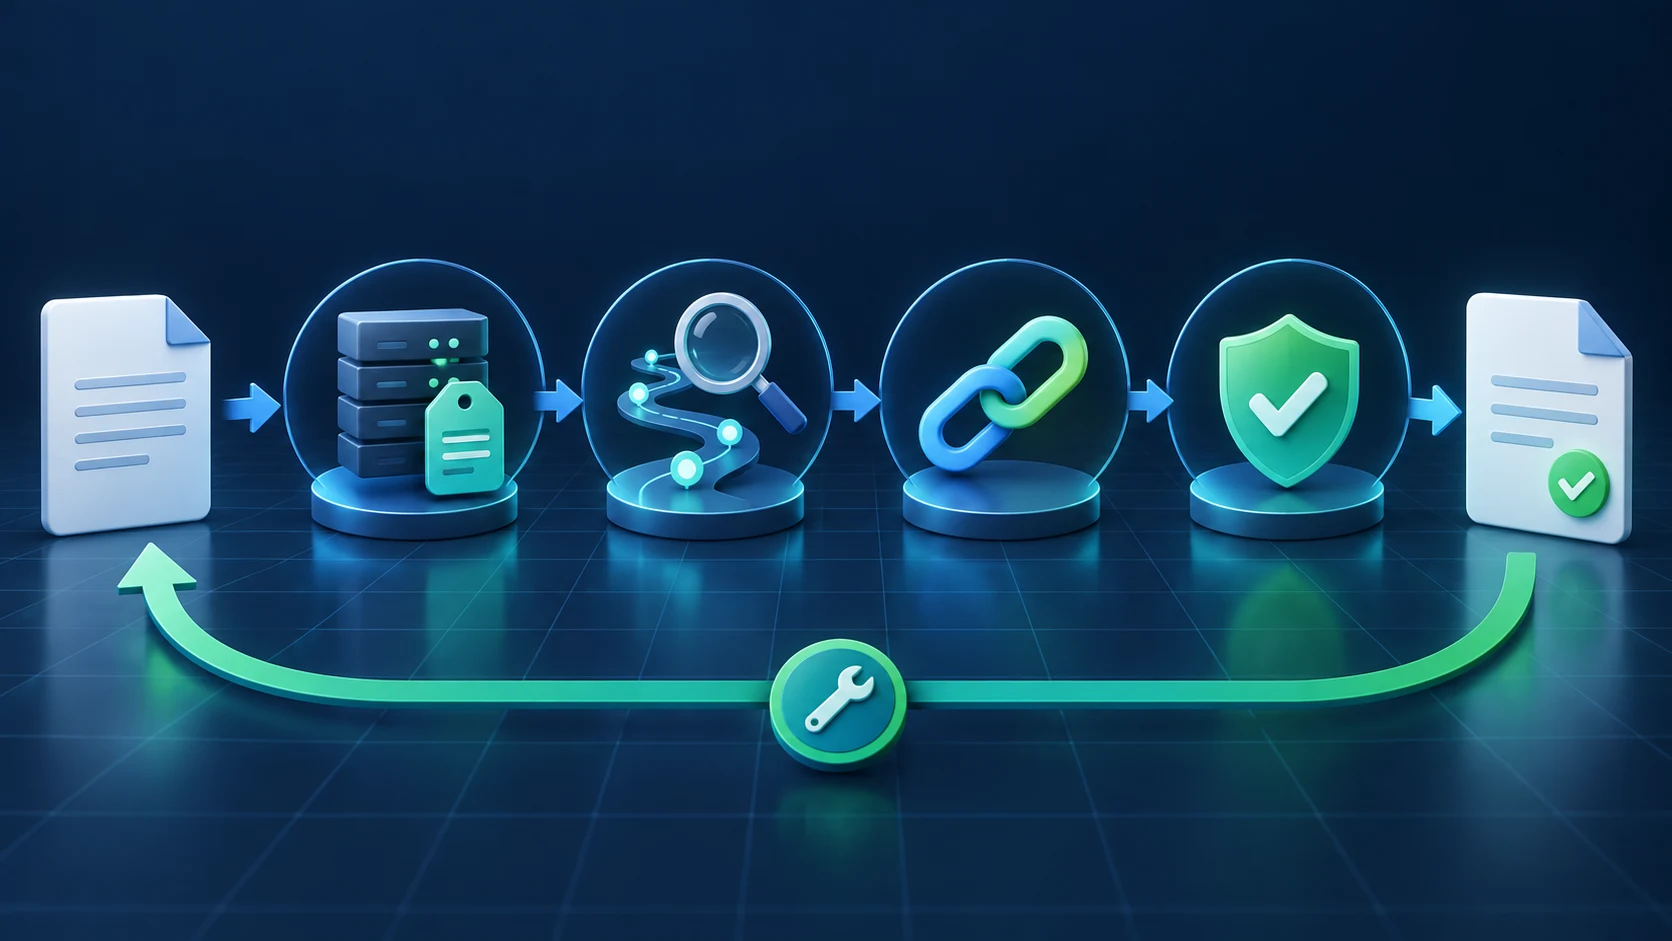
For the site-side evidence, a technical SEO crawler can help teams inspect links, redirects, canonicals, indexability, and sitemap behavior across the pages that introduce or support the document. Check raw PDF response headers separately when the crawl output does not expose the exact server directive. That division is useful: one pass catches the site pattern, and one precise response check proves what the file is actually serving.
Avoid the PDF SEO Mistakes That Create Ambiguity
These mistakes make it hard for a crawl, a content team, and search systems to agree on the right asset:
- Publishing an HTML article and PDF with the same primary answer. Pick a preferred URL and give the secondary version a narrower role, such as a download, appendix, or print copy.
- Using
robots.txtas an indexing switch. A crawl block is not the same as a reliable removal policy. Use the response-level directive that fits the goal, and leave enough access for a search engine to process that directive when appropriate. - Treating a scanned file as a complete web page. If people need to search, compare, quote, or navigate the resource, an HTML companion may be the better primary asset even when the PDF remains available.
- Adding a PDF to a sitemap with no contextual link. Sitemap inclusion is weaker than a clear page relationship. Put the resource in a relevant content, help, product, or research journey.
- Fixing one file instead of the publishing pattern. If an export template, CMS rule, or report workflow creates the same conflict repeatedly, document the intended owner rule and test a representative set on the next release.
Google's indexable file type guidance, robots directive documentation, and canonical URL guidance are the right references for the search-engine mechanics. Your own content inventory supplies the other half of the decision: whether the document actually deserves to be the page people find.
Turn the Decision Into an Owner-Ready Fix Queue
Make the result actionable rather than leaving a list of documents to revisit. One row per document pattern is usually enough when the underlying rule is shared.
| Queue field | Example acceptance condition |
|---|---|
| Page pattern | Every quarterly report has a stable owner page and a defined document role |
| Preferred asset | The HTML page or PDF is explicitly chosen for the substantive search task |
| Technical policy | Response status, canonical relationship, index directive, sitemap choice, and inlinks agree |
| Owner | Content, legal, product, CMS, or engineering owner can change the shared rule |
| Validation scope | Recrawl a representative document set and fetch headers from priority files |
| Search follow-up | Recheck the preferred URL after search systems have had time to process the release |
Use a canonical tags audit when the main risk is duplicate clustering, and an XML sitemap generator workflow when a document pattern is leaking unsuitable URLs into discovery. For the wider release baseline, the technical SEO workflow helps connect the document decision to redirects, internal links, indexability, and recurring crawl checks.
The durable outcome is not simply a PDF that can be indexed. It is a publishing system where each important answer has one clear owner, the surrounding technical signals agree with that owner, and the next crawl can prove the rule still holds.